The Enterprise ML Problem Training Serving Skew and Target Leakage
In enterprise machine learning deployments the majority of model failures do not stem from deficient neural network architectures or sub optimal hyperparameter tuning. They arise from systemic data engineering discrepancies between training and inference environments. This failure pattern known as training serving skew manifests in two destructive ways feature calculation divergence and point in time target leakage.
Feature calculation divergence occurs when offline training features are engineered using batch analytical engines like Apache Spark or BigQuery while real time inference features are calculated in Python or Java web services. Minor discrepancies in floating point precision timezone conversions null value imputations or window aggregations produce divergent feature distributions. At inference time the model receives data that differs subtly from what it observed during gradient descent causing prediction accuracy to degrade silently.
Target leakage occurs when historical training sets incorporate data generated after the occurrence of the prediction event. If a model predicts fraud at timestamp T but the feature pipeline joins customer transaction aggregates computed at timestamp T + 2 hours the model learns spurious correlations that fail completely in production. Feature stores solve both challenges by establishing a unified declarative abstraction across offline training and online serving infrastructure.
Architecture of a Modern Two Speed Feature Store
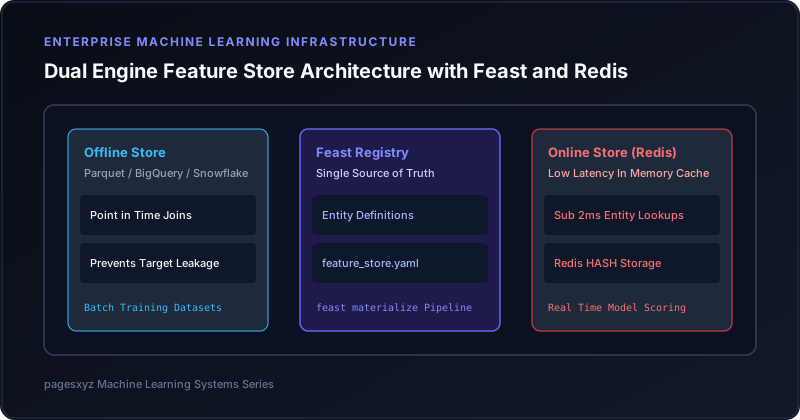
A production feature store is organized around a dual engine topology designed to satisfy two incompatible performance requirements:
- The Offline Analytical Store (High Throughput Batch Processing): Built on columnar object storage like Apache Parquet Delta Lake Snowflake or Google Cloud BigQuery. It stores complete historical logs spanning months or years enabling point in time correct joins across millions of training rows.
- The Online Serving Store (Ultra Low Latency Entity Lookups): Built on in memory key value infrastructure primarily Redis Cluster or Dragonfly. It maintains only the most recent feature values for each entity ID serving vector lookups to real time inference models with sub two millisecond latency under tens of thousands of requests per second.
Apache Feast acts as the declarative coordination layer tying these disparate storage backends together. Rather than writing custom extraction scripts data science teams define feature schemas entities and transformation pipelines in version controlled Python repositories. Feast manages schema registration automated materialization pipelines and unified feature vector retrieval APIs.
Point in Time Correct Joins AS OF Semantics Explained
The mathematical heart of an enterprise feature store is the point in time join often designated as an AS OF join. Consider a training dataset containing observation timestamps t_obs alongside entity keys like user_id and target labels:
Observation Event: user_123 made transaction of 150 USD at 2026-10-27 14:30:00To evaluate whether this transaction was fraudulent the feature store must retrieve the user historical transaction velocity (such as count of transactions in the previous 24 hours). The feature store must query the offline event table and select the most recent feature record whose timestamp t_feature satisfies:
t_feature <= t_obs AND t_feature >= (t_obs - TTL)Any record generated at 14:30:01 or later must be strictly excluded. By executing this logic deterministically across millions of historical events Feast eliminates lookahead bias ensuring that offline backtests match live production scoring conditions exactly.
Relational SQL Pattern for Point in Time AS OF Joins
To understand the query generation mechanics executed internally by Feast consider the following standard SQL windowing pattern executed over BigQuery or Snowflake:
WITH joined_events AS (
    SELECT
        obs.transaction_id,
        obs.user_id,
        obs.event_timestamp AS obs_time,
        feat.transaction_count_30d,
        feat.average_amount_30d,
        feat.risk_score,
        feat.event_timestamp AS feat_time,
        ROW_NUMBER() OVER (
            PARTITION BY obs.transaction_id, obs.user_id
            ORDER BY feat.event_timestamp DESC
        ) AS rank_order
    FROM observations obs
    LEFT JOIN user_features_historical feat
        ON obs.user_id = feat.user_id
        AND feat.event_timestamp <= obs.event_timestamp
        AND feat.event_timestamp >= TIMESTAMP_SUB(obs.event_timestamp, INTERVAL 30 DAY)
)
SELECT
    transaction_id,
    user_id,
    obs_time,
    transaction_count_30d,
    average_amount_30d,
    risk_score
FROM joined_events
WHERE rank_order = 1;
This query ensures that for every target observation event we attach the most recent feature vector strictly preceding the event timestamp preventing any possibility of data leakage.
Production Configuration and Implementation with Feast and Redis
Setting up an enterprise feature store requires configuring a declarative repository. The central configuration file feature_store.yaml specifies both storage backends and connection pooling parameters:
# feature_store.yaml
project: enterprise_production_store
registry: data/registry.db
provider: local

offline_store:
  type: file
  # In enterprise clusters, configure Snowflake, BigQuery, or Redshift:
  # type: snowflake / bigquery

online_store:
  type: redis
  connection_string: redis://:secure_redis_auth@redis-cluster.internal:6379/0
  key_ttl: 86400  # 24 hour TTL for inactive entity eviction
Declarative Feature Definitions in Python
Data science teams define features using Feast Python definitions specifying entities data sources and feature views:
from datetime import timedelta
from feast import (
    Entity,
    FeatureView,
    Field,
    FileSource,
    ValueType
)
from feast.types import Float32, Int64, String

# 1. Define Entity
user_entity = Entity(
    name="user_id",
    value_type=ValueType.INT64,
    description="Unique user identification key"
)

# 2. Define Batch Source
user_stats_source = FileSource(
    name="user_daily_stats_source",
    path="data/user_features.parquet",
    timestamp_field="event_timestamp",
    created_timestamp_column="created_timestamp"
)

# 3. Define Feature View with TTL
user_daily_stats_view = FeatureView(
    name="user_daily_stats",
    entities=[user_entity],
    ttl=timedelta(days=7),
    schema=[
        Field(name="transaction_count_30d", dtype=Int64),
        Field(name="average_transaction_value_30d", dtype=Float32),
        Field(name="chargeback_rate_90d", dtype=Float32),
        Field(name="risk_score", dtype=Float32),
    ],
    online=True,
    source=user_stats_source
)
Online Low Latency Feature Retrieval Implementation
At inference time the web service hosting the model needs to retrieve pre calculated features for an incoming request. Using the Feast Python SDK client the application requests feature vectors directly from Redis:
from feast import FeatureStore
import time

# Initialize store from declarative repository
store = FeatureStore(repo_path="./feature_repository")

def get_realtime_inference_features(user_id: int) -> dict:
    start_time = time.perf_counter()

    # Request features from Redis online store
    feature_vector = store.get_online_features(
        features=[
            "user_daily_stats:transaction_count_30d",
            "user_daily_stats:average_transaction_value_30d",
            "user_daily_stats:risk_score"
        ],
        entity_rows=[{"user_id": user_id}]
    ).to_dict()

    elapsed_ms = (time.perf_counter() - start_time) * 1000.0
    print(f"Online feature fetch completed in {elapsed_ms:.2f} ms")
    return feature_vector
Inside Redis Feast stores entities as Redis HASH keys structured with project prefixes and entity hashes. Because queries map directly to Redis HMGET operations lookup latency scales deterministically below two milliseconds regardless of whether the offline dataset holds terabytes of historical logs.
Real Time Stream Ingestion with Change Data Capture and Kafka
While batch feature stores materialize once daily or hourly fraud detection and dynamic pricing systems require real time feature freshness. To achieve sub second feature updates enterprises integrate Change Data Capture (CDC) with Debezium and Apache Kafka.
Whenever a customer completes an action in a transactional PostgreSQL database Debezium captures the database write ahead log (WAL) and publishes a JSON or Avro event to a Kafka topic. A streaming consumer evaluates real time aggregations (such as rolling 5 minute spend) and pushes updates directly to Redis via Feast streaming feature views. Simultaneously events are dumped to S3 or GCS data lakes for offline training joins maintaining strict dual engine synchronization.
Redis In Memory Data Modeling and Memory Compression
When serving hundreds of millions of users in memory RAM cost in Redis clusters becomes a primary operational constraint. Unoptimized key value structures cause massive memory bloat.
To maximize memory efficiency production feature stores enforce Redis ziplist and listpack configurations:
- Hash Encoding Thresholds: Setting
hash-max-listpack-entries 512andhash-max-listpack-value 64ensures small hashes remain in compact contiguous byte arrays saving up to 60 percent of pointer overhead. - Volatile LRU Eviction: Configuring
maxmemory-policy volatile-lruensures that Redis automatically discards inactive entity records when memory pressure peaks without dropping permanent metadata keys.
Monitoring Feature Drift and Population Stability Index
Over time customer behaviors shift and external economic environments evolve causing feature distributions to drift away from training baselines. Production feature stores run automated daily validation evaluating Population Stability Index (PSI) across online features:
PSI = sum( (Actual_i - Expected_i) * ln( Actual_i / Expected_i ) )Where Expected_i is the percentage of training observations in quantile bucket i and Actual_i is the percentage observed in online inference logs. A PSI score above 0.2 indicates severe population drift triggering automated model retraining alerts.
Production Feature Materialization Pipelines and Backfilling at Scale
While online serving retrieves individual entity vectors with microsecond response times populating the Redis online store requires robust bulk materialization pipelines. When spinning up new models or introducing fresh engineered features teams must backfill months of historical aggregates without degrading live inference latency.
Apache Feast provides distributed materialization engines orchestrated through Apache Spark or Ray. Rather than issuing single record write commands Feast groups entity updates into parallelized multi row batches. Inside Redis the materialization engine utilizes Redis Pipelining grouping thousands of HSET commands into single TCP network round trips. This increases write throughput from five thousand writes per second to over three hundred thousand writes per second per Redis shard.
Furthermore production pipelines partition materialization jobs across explicit time intervals:
feast materialize-incremental $(date -u +"%Y-%m-%dT%H:00:00")Incremental materialization inspects the high watermark timestamp recorded in the Feast registry writing only records that have changed since the previous execution cycle. This reduces network ingress bandwidth across cloud regions and prevents memory contention on production Redis nodes.
Summary of Production Best Practices
When architecting enterprise feature stores teams should enforce strict operational rules:
- Version Control Definitions in Git: Treat feature definitions identically to application code requiring peer review and continuous integration tests before schema registration.
- Configure Explicit TTLs: Always define Time To Live parameters on online feature views to prevent unbounded memory growth in Redis clusters.
- Monitor Feature Drift: Track online feature value distributions against offline baselines to detect data pipeline corruption before model predictions degrade.
For data scientists and ML infrastructure engineers seeking advanced methodological grounding review our technical study on Causal Inference and Double Machine Learning in Production and explore machine learning infrastructure roles on the PagesXYZ Career Platform.